
What is a Data Flywheel? A Guide to Sustainable Business Growth
A data flywheel is a self-reinforcing loop in which a business uses its proprietary data to power AI products and decisions, captures how people respond, and feeds that new data back in to improve the next round. Each turn makes the AI more effective and the data harder for competitors to copy.
“The important thing about the chat bot, the customer service, is partly about the fact that you can automate. But it’s mostly about the data flywheel. You want to capture the conversation. You want to capture the engagement in your data flywheel. It’s going to create more data, of course. We’re probably seeing data expanding about 10x every five years. Wow.”
Jensen Huang, CEO, NVIDIA
Most organizations are now investing in artificial intelligence (AI). The data flywheel is the framework that turns that investment into an advantage that compounds over time.
Some organizations already run parts of a data flywheel without calling it one. Naming the framework helps you see which parts are missing.
Jensen Huang of NVIDIA has been one of the concept’s most prominent advocates.
This article draws on a talk Yali Sassoon, CTO and co-founder of Snowplow, gave on data flywheels at Data Science Connect. It covers what a data flywheel is, how companies use one, and practical steps for building your own.
What is a Data Flywheel?
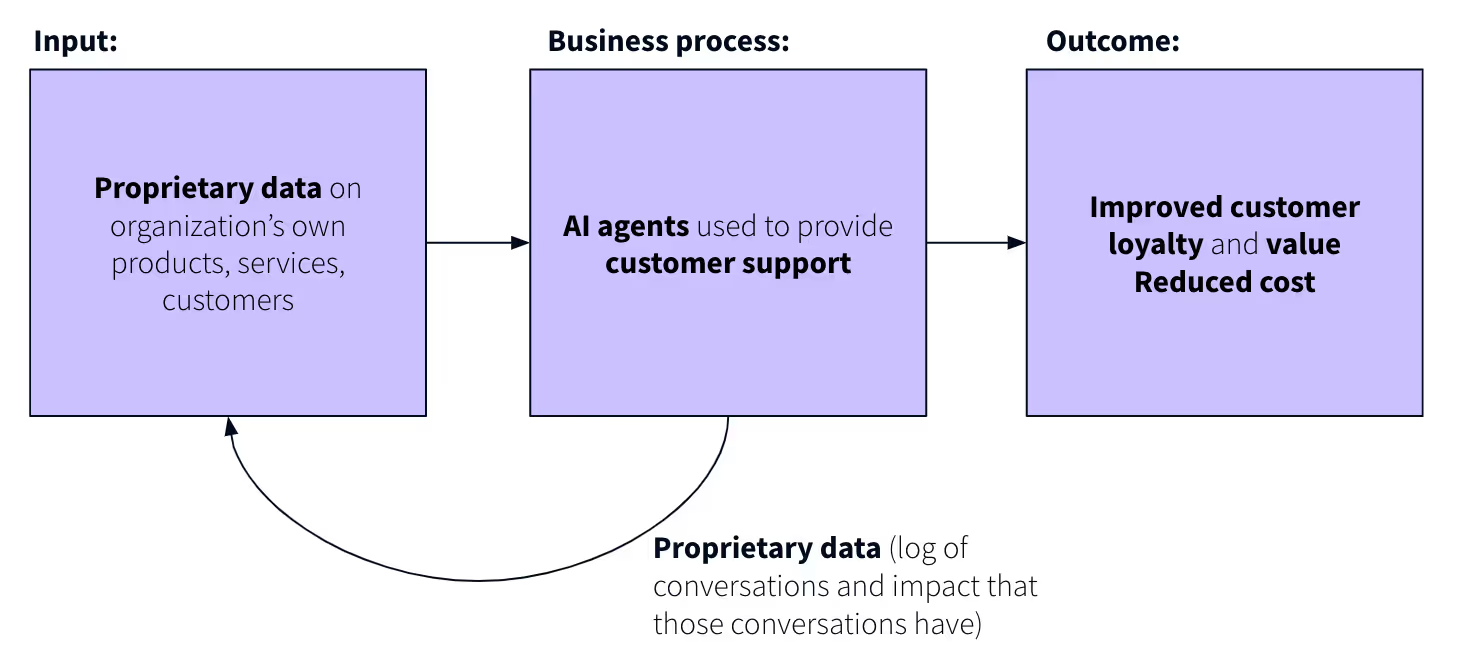
A data flywheel is a strategic framework for creating sustainable competitive advantage through AI applications.
It's a self-reinforcing system in which proprietary data, your organization's "special fuel," powers AI that delivers a service, such as handling customer support, optimizing content placement, or designing hardware like GPUs.
The flywheel effect comes from what happens next: as your AI provides these services, you capture detailed data about both what it did and what effect it had.
This new data becomes additional proprietary fuel that feeds back into the system, enabling your AI to continuously improve its performance in ways that would be difficult for competitors to replicate with generic data sets.
Think of it like a wheel with unique properties. The initial push takes significant effort: gathering your proprietary data and implementing AI services. But once the wheel starts turning, each rotation generates more data about your AI's performance and impact.
This data feeds back into the system, so the next rotation starts from a better position. Over time, your AI's effectiveness increases with each iteration, and because the data is proprietary, competitors find it harder to catch up.
The difference from a basic AI implementation is that a data flywheel captures the results of its own AI decisions and uses them as new data to learn from, so the advantage compounds over time.
Why Do Data Flywheels Matter?
1. Sustainable Competitive Advantage
"The flywheel of machine learning is the most important thing. A lot of people don't even realize that it takes AI to curate data to teach an AI. We have agents helping design chips - Hopper wouldn't be possible, Blackwell wouldn't be possible."
Jensen Huang, CEO, NVIDIA
Data flywheels help organizations build a competitive advantage that lasts. NVIDIA is one example.
NVIDIA has accumulated years of chip design data. As an early adopter of large language models for chip design, it has kept adding to that proprietary data.
The company uses this historical design data to train the AI that helps design new chips. Better AI improves chip design, which generates more design data, which in turn improves the AI.
This puts newcomers at a double disadvantage: they not only lack the historical design data needed to train competitive AI systems but also can't match the AI-assisted design capabilities NVIDIA has developed over years of iteration.
This data advantage compounds over time, making it increasingly difficult for new entrants to compete effectively in the GPU market.
2. Improved Performance and Efficiency
Data flywheels can produce large efficiency gains, but they improve only the outcomes you feed back into them. Klarna’s customer service assistant shows both the gains and the risk.
Klarna built an AI assistant on OpenAI’s models to handle support conversations in more than 35 languages, trained on its own past conversations and service documents. In 2024, Klarna reported that response times had fallen from 11 minutes to 2, that the assistant was doing the work of 700 full-time agents, and that it expected a $40 million profit improvement.
In May 2025, CEO Sebastian Siemiatkowski said that cost had been weighted too heavily in judging the program and that service quality had dropped as a result. Klarna began hiring human agents again so customers could always reach a person.
The lesson for anyone building a flywheel is that it gets better at whatever you measure. If the data you capture tracks cost per conversation but not whether the customer’s problem was solved, each turn makes the system cheaper without making it better. That’s why the action tracking element below records whether each interaction succeeded, as well as what happened.
3. Continuous Learning and Improvement
Data flywheels improve your AI’s performance over time. The scale of this improvement is significant. As Jensen Huang notes, these systems are driving data expansion “about 10x every five years” through continuous feedback loops.
We’re seeing this impact across multiple industries. In his talk, Yali shared how one media organization evolved their capabilities: starting with algorithms to measure content monetary value, they progressed to optimizing content placement, then automated content positioning through news cycles to maximize revenue.
This eventually led to algorithms for paywall decisions and dynamic subscription pricing.
Going back to our original example, NVIDIA's GPU design process shows the ultimate potential. Their system continuously learns from countless design iterations, making it nearly "impossible to design new generations of GPUs without AI assistance."
The system improves with each iteration. Each interaction generates new data that feeds back into the system, and competitors without that data find the cycle hard to match.
It works like compound interest: each round of learning builds on the last.
Building Your Data Flywheel: 5 Essential Elements
1. Proprietary Data Foundation
Every effective data flywheel starts with rich proprietary data. This information is unique to your organization and is difficult for your competitors to replicate.
The opportunity is growing. As Jensen Huang notes, organizational data is expanding "about 10 times every five years." That's a reason to start capturing and using your proprietary data now, before the volume becomes hard to manage.
This might include:
- Customer behavioral data
- Operational data related to manufacturing, supply chain and fulfillment
- Design data (product design, machine design)
- Knowledge bases (documentation, manuals)
- Market research
This element matters most. Everyone has access to the same handful of foundation models, so businesses need to think about what makes them unique and what proprietary data they can use to stand apart from the competition.
2. Real-Time Architecture
Once you have identified the proprietary data you want to gather, it’s time to think about your data architecture.
For your data flywheel to thrive, you need to have real-time architecture in place. Why is this? Well, data flywheels are all about momentum. The faster you can move through the OODA loop (observe, orient, decide, act), the faster your system learns and improves.
A real-time architecture lets you:
- Make instant decisions using the latest user data
- Capture the impact of those decisions immediately
- Feed results back into your AI systems quickly
- Stay ahead of competitors by learning faster
- Scale your operations without losing speed
It’s easier to build a real-time architecture than it used to be. Streaming platforms such as Apache Kafka and Confluent move events at speed, and Databricks Lakeflow pipelines (formerly Delta Live Tables) process them.
Snowplow Signals adds a real-time customer context layer to this architecture. It computes behavioral attributes, such as the latest product a customer viewed or how many pages they’ve seen this session, from the live event stream as events arrive, and serves them to your applications and AI agents. The data doesn’t have to land in a warehouse first.
3. Feature Pipeline Development
Having a vast amount of raw, unstructured data stored in a data lake isn’t enough for your data flywheel. You need to turn it into something meaningful that your AI can learn from.
In his talk, Yali demonstrated this with a customer email example: rather than just collecting entire emails, their system breaks them down into specific features like humor, voice, length, and social proof. This structured approach helps the AI understand what works and what doesn't.
A good feature pipeline helps you:
- Break down complex data into learnable characteristics
- Create clear metrics to measure success
- Help AI systems learn faster from each interaction
- Test and improve your models quickly
Think of it like teaching a new language. Instead of handing someone entire books, you start with basic vocabulary and grammar. Similarly, feature pipelines break down your raw data into "vocabulary" that your AI can understand and learn from.
4. Data Quality and Governance
"Data doesn't rain down from clouds," as Yali explained. It has to be deliberately produced, with quality and governance built in from the start. That matters more when AI, not a person, acts on the data.
Quality and governance needs focus on:
- Ensuring both humans and AIs understand exactly what the data means
- Building trust through consistent data quality
- Maintaining clear rules about how data can be used
- Following compliance requirements throughout all processing
Think of it like manufacturing: you wouldn't build a car without quality controls. The same applies to your data flywheel: quality and governance aren't extra features, they're essential foundations.
5. Tracking Customer and Agent Actions
Lastly, your data flywheel needs tracking that covers both customers and AI agents. It’s no longer a case of understanding customer journeys through user behavior - you also need to track what your AI agents do.
Organizations often miss this element. Even though many of them are collecting this data type, they often fail to use it to drive systemic improvements in their application performance.
Every journey involves multiple AI agent decisions happening behind the scenes predicting what a customer might buy, personalizing emails, and optimizing timing of communications.
Therefore, your tracking needs to capture:
- What the customer does (like browsing products)
- What the AI agent decides (like product recommendations)
- How customers respond to AI agent decisions
- Whether these interactions lead to success
Think of it like watching a tennis match: you need to see both players' moves to understand the game. Similarly, you need to track both user and AI agent actions to understand and improve your customer interactions.
What Is an Agent Flywheel?
An agent flywheel is a data flywheel built around an AI agent. The agent acts on what it knows about a customer, the customer responds, and that response becomes data that improves the agent’s next decision. The loop has two halves, and both run on behavioral data.
Grounding the Agent in Real-Time Context
Before an agent responds, it needs to know what the customer is doing right now, such as what they’ve browsed, searched for, or added to their cart in this session. Snowplow Signals provides this as Agentic Context, a live record of a user’s recent session activity that the agent can read as structured JSON or as a plain-language narrative.
Capturing Outcomes and Feeding Them Back
After the agent acts, you need a record of what happened next. Snowplow Customer Data Infrastructure tracks what the customer did, which tools the agent called, and the decisions it made along the way, then delivers that data in real time to your warehouse, lake, or stream. Teams use it to evaluate the agent and feed the results back into its models. Because Signals reads the same event stream, the outcome of one interaction also becomes part of the context for the next.
Getting Started with Your Data Flywheel
1. Identify your unique data advantages
2. Choose a focused initial use case
3. Build real-time data collection systems
4. Implement quality controls from the start
5. Create clear feedback loops
6. Monitor and measure results
7. Expand gradually based on success
Other Industry Examples to Inspire Your Flywheel
Retail: Building a Smart Shopping Experience
Several of our retail customers are demonstrating how data flywheels can transform the entire customer journey. By layering multiple AI algorithms throughout their shopping experience, they personalize more of the experience over time:
- Homepage algorithms analyze available inventory, trending items, and user preferences to showcase the most relevant content and offers
- Search functionality learns from user behavior to deliver personalized results
- Product pages use AI to recommend complementary or alternative items based on purchase likelihood
- Checkout experiences suggest both related and unrelated items to help customers complete their baskets
What makes this a data flywheel is that each algorithm's learning compounds over time. The deep understanding of customer behavior developed in one area accelerates improvements across the entire journey.
Success with homepage personalization, for instance, provides valuable insights that speed up the development of checkout recommendations.
Media: Balancing Breadth and Depth
We’re also seeing some of our media customers implementing similar flywheels that balance content discovery with deep engagement. Their systems combine two types of algorithms:
- "Breadth" algorithms that help users explore diverse content options
- "Depth" algorithms that guide users deeper into specific topics of interest
These algorithms are built into the user interface, giving readers the freedom to either explore broadly or dive deep into particular subjects. The system continuously learns from growing volumes of user interaction data, becoming increasingly adept at striking the right balance for each individual reader.
This creates a feedback loop: as users engage more with the content, the algorithms get better at understanding and serving their preferences, which in turn drives more engagement and generates more learning data for the system.
Conclusion
Now you understand the basic elements of a data flywheel and the high level steps to get started, it’s time to put theory into practice. While the initial effort may be substantial, the long-term benefits make it a worthwhile investment for any organization that wants a lasting competitive advantage.
The key is to start small, focus on quality, and build momentum over time. Remember, every successful data flywheel started with a single turn of the wheel.
Ready to Build Your Data Flywheel?
To learn more about data flywheels and how to build one, watch Yali's full Data Flywheel presentation.
Snowplow Signals is a real-time customer context layer for your AI agents and personalized experiences. Start a free Snowplow Signals trial.
Data Flywheel FAQs
How can an agent flywheel improve customer engagement?

An agent flywheel improves customer engagement by making each interaction teach the agent something about the next one. Snowplow supports both halves of that loop. Snowplow Signals grounds the agent in what a customer is doing right now through Agentic Context, a live record of their recent session activity. Snowplow Customer Data Infrastructure captures the outcomes, including how customers respond to the agent, and delivers them in real time to feed back into your agent models.
What is an AI flywheel?
An AI flywheel is a data flywheel built around an AI model or agent. The AI serves users, their interactions and outcomes are captured as new data, and that data is used to improve the AI, so each cycle makes the next one more accurate. The two terms are often used interchangeably. AI flywheel puts the emphasis on the model, while data flywheel puts it on the proprietary data that keeps the loop turning.
What do you need to build a data flywheel?
You need five things to build a data flywheel: proprietary data competitors can't copy, infrastructure that collects and processes it in real time, features your models can learn from, quality and governance controls, and tracking of what your AI decides and how users respond. Most teams start with one use case, such as product recommendations, and close the loop there before expanding to the next.
How does a data flywheel work for agentic AI?
For agentic AI, a data flywheel records what the user did, what the agent did, and why, then uses those records to improve the agent. That means tracking user messages, the tools the agent called and whether they succeeded, and the decisions it made along the way. Teams find where the agent fell short and refine its prompts, tools, and guardrails. Snowplow Customer Data Infrastructure can capture all three layers.