
The Power of Behavioral Data for Real-Time Personalization
Real-time personalization changes what a person sees, such as content, recommendations, offers, or an AI agent's response, based on what they are doing in their current session, not only on what they did before. It depends on first-party behavioral data that is captured as it happens and turned into attributes an application can act on during the same visit.
Organizations are starting to realize the value of real-time data to power data products with increasing levels of personalization and tailored experiences.
The combination of real-time data and AI enables powerful traditional applications, including:
- User Segmentation: Classifying a customer based on various features and assigning them to a cohort
- Anomaly Detection: Identifying anomalies or outliers in real-time, enabling rapid detection of fraud, system failures, or security breaches
- Targeted Advertising: Combining a user's current real-time context and historical data to determine the best ads to serve or suppress
These can add significant business value in the right context, but some applications are only possible with generative AI and AI agents, such as:
- Dynamic Content Generation: Create personalized content like product descriptions, marketing emails, article headlines and placement, or reports on the fly based on a user's real-time data and preferences
- AI Agents and Assistants: Respond to each user based on what they are doing in the current session, such as what they've viewed, searched for, or added to their cart
- Adaptive User Interfaces: Generative models could dynamically adapt the user experience of apps/websites based on how the user interacts and navigates in real-time, personalizing layouts, workflows and micro-copy
Wherever a business is in adopting these capabilities, the bar is rising. Features that used to set a business apart are quickly becoming what customers expect.
Whereas cohort-level personalization used to be acceptable, now users are coming to expect their unique preferences to be accounted for in their experience. In the context of highly competitive or even commoditized products or services, effective use of the technology could therefore be the deciding factor between winning or losing a customer to another business.
Generative AI and AI agents are speeding this up.
To personalize at this level, it is necessary to build sophisticated customer profiles, incorporating various sources of customer data, the most significant of which and arguably the most underserved is behavioral data, both structured and unstructured. The question then becomes how to dynamically incorporate behaviors into these customer profiles in order to maximize opportunities to delight customers at every touchpoint.
However, this is a challenging engineering feat to achieve and must also be executed within the bounds of data privacy requirements. Snowplow’s customer data infrastructure (CDI) is intentionally designed to support customers in meeting this challenge, regardless of their approach to leveraging AI within their data products.
Architectures to Support Real-Time Personalization
We can think about the architectures to support real-time personalization as spanning three distinct eras:
- Initial Separation Era: There was a clear delineation and separation of concerns between data platforms (for analytics) and stream processors (for low-latency pipelines) as two distinct and separate architectures
- Lambda Era: A single overarching architecture that consisted of a real-time component for operational use cases and an analytical component for slower data warehousing workloads. However, this still required maintaining multiple versions of the same data across those components, which would achieve "eventual consistency" by rationalizing the versions later
- Unified Era: Blurring of lines between analytics and streaming workloads: data platforms have capabilities allowing unified logs and true real-time analytical systems (Databricks Lakeflow Declarative Pipelines and Snowflake Dynamic Tables)
Many organizations that formerly would have defaulted to a Lambda architecture now have options. The choice is an important one and would take significant effort to unwind. As such, it's important to consider the benefits of each approach:
Centralizing onto a Data Platform:
- Allows a simplified infrastructure as opposed to two independent, parallel systems. This theoretically halves the operational overhead and reduces the points of failure to be addressed
- No segregation of batch/analytical and streaming datasets that would otherwise need to be integrated together requiring further data engineering effort
- Governance and security only need to be applied to a single pipeline rather than being replicated and then maintained to ensure consistency between two separate data flows
- A layer of abstraction is placed on top of complex streaming infrastructure resulting in a much friendlier learning curve for FTEs given that these platforms leverage SQL. This minimizes the need for data engineering expertise and means that analytics experts are better equipped to self-serve
- Overall, this approach entails less complexity and effort to build and maintain relative to traditional streaming systems, which in turn facilitates easier iteration, mitigation against unforeseen impacts of changes, and compressed time to value
Utilizing a traditional streaming solution offers benefits, which are often the converse of the above:
- Dedicated expertise optimizing for high-volume, low-latency streaming, potentially offering advanced, fine-tuned capabilities tailored for mission-critical real-time personalization use cases
- Purpose-built architectures designed from the ground up to handle unique challenges of real-time data like high throughput, fault tolerance, and strict latency requirements for better performance and reliability
- Mature ecosystem with wide range of specialized third-party tools, integrations and larger developer community providing diverse solutions and support for complex streaming needs
- Conversely to the above: flexibility to independently scale and optimize separate batch and streaming workloads based on unique requirements
Do models need to retrain on every event?
A common misconception about real-time personalization and machine learning models is that new information should constantly feed into and retrain the algorithm on a continuous basis, i.e., the model is always up to date with all new data that the business has captured.
In reality, this isn't practical. Firstly, it would likely be prohibitively expensive: this would require a considerable amount of compute, even with models that can iteratively incorporate new data rather than taking a "drop and recompute" approach of retraining on the dataset as a whole on every iteration.
If the value generated by this approach was proportional to this cost, then it would be viable, but a training dataset by definition should be very large. Continuous retraining would entail adding relatively marginal amounts of data to the initial training dataset, making negligible difference to the decisions or "rule set" that it generates.
To illustrate this with an example, take the use case of a real-time personalization engine. As a starting point, you may look to train a recommender on months of content selection behaviors. Incrementally retraining the model on additional minutes, hours, or even days worth of data would be very unlikely to influence the resultant decisions the model would make.
It's important therefore to establish that the real-time element of a behavioral data pipeline usually acts as a "triggering mechanism" as opposed to a live feed into a machine learning data product.
The event would usually be sent to an API, which in turn queries a precalculated rule set. That rule set is then retrained periodically. The exact frequency of retraining should take into account the trade-off discussed above.
It could in fact be optimized over time, i.e., are the results from retraining on a daily basis worth the cost in terms of favorable outcomes (e.g., conversions from a recommender) relative to retraining weekly?
There will be an inflection point of diminishing returns at which a higher frequency yields a negligible uplift in model performance.
Snowplow's Role in These Topologies
Snowplow is a real-time customer context layer. Snowplow Customer Data Infrastructure collects, validates, enriches, and delivers first-party behavioral data from your websites and apps to your warehouse, lake, or real-time streams. Because it records what users actually do, this data is a reliable and predictable signal of intent.
Snowplow Signals turns that event stream into user attributes in real time and serves them to your applications and AI agents over an API, so they can respond to what a user is doing during the session. Signals grounds each decision in real-time context, and Customer Data Infrastructure captures the behavioral outcomes that feed back into your models.
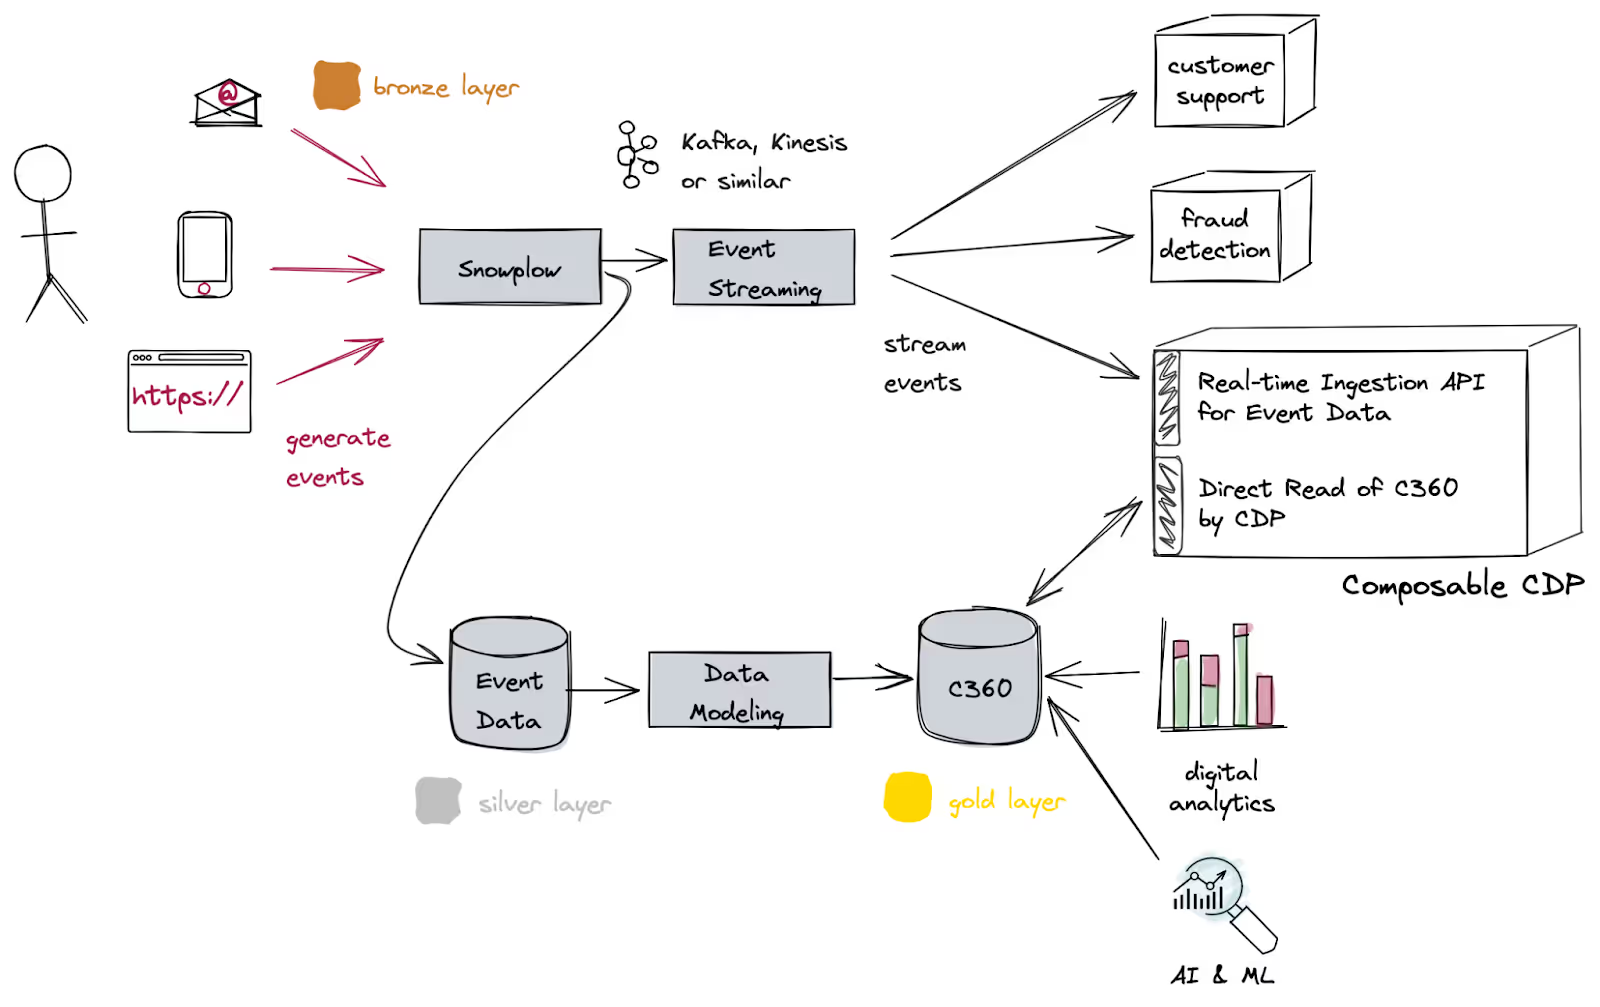
Real-Time Personalization: Flexible Implementation Options
We provide our customers with full optionality on their approach to real-time data applications.
Using Snowplow Signals for in-session personalization
Snowplow Signals calculates attributes from your event stream as events arrive, such as the last product a user viewed or the number of page views in a session, so you don't need to build and run your own stream processing for in-session use cases. It can also sync pre-calculated values, such as CRM fields or purchase history, from your warehouse. Your applications retrieve attributes over an API, or subscribe to triggers that fire when a user meets criteria you define. For AI agents, an Agentic Context provides a rolling record of a user's recent activity, which agents can read through the API or the Signals MCP Server. You can start on the Signals free trial.
Powering the Lambda Architecture Approach
If you'd rather run your own streaming solution in a Lambda-style architecture, you have three options to consume our data feed and integrate it with downstream destinations:
- Use event forwarding: Filter, transform, and send events in real time, either to third-party platforms through pre-built integrations for tools such as Braze, Bloomreach, Amplitude, Mixpanel, and the Meta Conversions API, or to your own destinations, such as Kafka, with custom transformations.
- Use our analytics SDKs: Allowing data engineers to use popular languages (e.g., Python, JavaScript, Scala) to parse Snowplow events and transform them from the native TSV format of our enriched stream to JSON. This tends to be a more popular format to manipulate and plug into downstream services, as the engineer sees fit.
- Build a custom integration: Develop bespoke data pipelines and processing logic to handle the ingested data according to the customer's unique needs. Stream processing frameworks such as Apache Flink, or a managed service like Amazon Managed Service for Apache Flink, are common choices here.
Powering the Unified Architecture Approach
If you're consolidating onto a data platform, Snowplow loads events with low latency into both Snowflake and Databricks. The Snowflake Streaming Loader writes to Snowflake using the Snowpipe Streaming API and is supported across all clouds. Data lands in Snowflake in seconds. The Databricks Streaming Loader loads events into Databricks using Lakeflow Declarative Pipelines.
The best choice will come down to the trade-off necessary when optimizing for either out-of-the-box functionality and time-to-value (i.e., event forwarding) or latency (i.e., the analytics SDKs, custom integrations).
Real-time personalization with Snowplow
Data platforms and AI agents now make it possible to personalize each experience in real time, but only with behavioral data that is captured as it happens and turned into context an application can use. Snowplow Customer Data Infrastructure captures that data, and Snowplow Signals turns it into real-time context for your applications and AI agents, with options to fit the infrastructure you already run.
Companies like Autotrader and Secret Escapes use Snowplow to deliver personalized experiences in real time.
Real-time personalization FAQs
What is a personalization engine?

A personalization engine is the system that decides what each person sees, such as which product, article, offer, or message to show, using rules or machine learning models. Its decisions are only as current as the data it receives. Snowplow Signals gives a personalization engine up-to-date behavioral context by calculating user attributes from live events and serving them over an API, so models trained on historical data can respond to what a visitor is doing now.
What is behavioral segmentation?
Behavioral segmentation groups people by what they do, such as the pages they view, the features they use, how often they buy, or how recently they visited, rather than by demographics. Real-time personalization updates those groups during the session instead of overnight. Snowplow Signals calculates behavioral attributes from live events, such as how many pages a visitor has viewed this session, so an application can group and respond to them while they are still on the site.
How can I implement real-time personalization on my website?
You implement real-time personalization by capturing behavioral events as they happen, turning them into user attributes during the session, and serving those attributes to the rules, models, or agents that decide what to show the user. With Snowplow, trackers send events to your pipeline and Snowplow Signals calculates attributes, such as the last product viewed, from the live event stream. Your site retrieves them over an API or subscribes to triggers that fire when a visitor meets criteria you define.
Can you personalize experiences for anonymous visitors?
Yes, you can personalize for anonymous visitors by keying attributes to the cookie-based user or session ID that Snowplow attaches to every event by default. Snowplow Signals calculates those attributes before a visitor ever logs in. When they do log in, Snowplow Identities attributes their earlier anonymous events to the authenticated user, within the same session and across sessions and devices, so the history carries over.
How can AI agents use real-time behavioral data to personalize responses?
AI agents use real-time behavioral data as context, so a chatbot or AI assistant knows what the user has viewed, searched for, or added to their cart in the current session before it responds. Snowplow Signals provides this as an Agentic Context, a rolling record of a user's recent activity returned as JSON or as a plain-language narrative. Agents can read it through the API or discover it as a tool through the Signals MCP Server.
What are the challenges of real-time personalization and how to overcome them?
The main challenges are inconsistent tracking data, recognizing the same person across sessions and devices, and getting fresh behavioral context to applications and AI agents fast enough to use during a visit or session. Data and personalization engineering teams address them by validating events against schemas at collection, resolving identities as events arrive, and calculating attributes from the event stream instead of waiting for warehouse batch jobs. Snowplow handles these three steps.