
The 14 best free and open source analytics tools (2026)
It's fairly easy to find the top SaaS analytics tools. Search for "analytics tools" and bingo.
Finding free and open source analytics tools that are still maintained is harder. Some popular picks from a few years ago have gone quiet.
So here's our current list, grouped by what each tool does, with its strengths and weak spots. One caveat up front: open source is free to download. Running it isn't.
The short answer, by job:
- Web analytics: Matomo, or Plausible and Umami for something lighter.
- Product analytics: PostHog, or Countly for mobile apps.
- Experimentation: GrowthBook.
- Data validation and monitoring: Great Expectations and Elementary.
- Collecting behavioral data into your warehouse: Snowplow.
- Dashboards and BI: Metabase for ease of use, Superset for depth.
Table of contents
We've grouped the 14 tools into 9 categories:
- Customer data infrastructure
- Open source product and web analytics tools
- Open source A/B testing tools
- Open source reverse ETL tools
- Open source data validation tools
- Open source analytics engineering tools
- Open source anomaly detection tools
- Open source databases
- Open source data visualization tools
Also in this guide:
- The 14 tools at a glance
- How we chose these tools
- Open source vs hosted platforms
- What to look for in a free tool
- Frequently asked questions
The 14 tools at a glance
| Tool | Best for | License | Free option | Main limitation |
|---|---|---|---|---|
| Snowplow | Collecting and validating behavioral data for your warehouse | Trackers: Apache 2.0. Pipeline: source-available | 14-day CDI Cloud trial, or the Signals free tier | No free production pipeline you run yourself |
| Countly | Mobile app analytics | AGPL-3.0 with added terms | Countly Lite, self-hosted (non-commercial license) | Lite leaves out Enterprise features |
| PostHog | Product analytics | MIT outside ee/ | Cloud free tier, or self-hosted hobby deploy | No support for self-hosted installs |
| Matomo | A Google Analytics alternative | GPL-3.0 | Self-hosted | You run the PHP and MySQL stack |
| GrowthBook | A/B testing and feature flags | MIT outside enterprise directories | Self-hosted, or GrowthBook Cloud | Results depend on your event data |
| Multiwoven | Reverse ETL | AGPL-3.0 | Self-hosted | Younger project; check its connectors |
| GX Core | Data validation | Apache-2.0 | Self-hosted Python library | Needs Python skills |
| dbt | SQL transformations | Apache-2.0 | dbt Core, self-hosted | Transforms only; no extract or load |
| Elementary | Anomaly detection in dbt projects | Apache-2.0 | Elementary OSS | Needs dbt; some features Cloud-only |
| Apache Druid | Sub-second queries on real-time data | Apache-2.0 | Self-hosted | Many services to run in production |
| TimescaleDB | Time-series data in PostgreSQL | Apache-2.0, some features under the Timescale License | Self-hosted | Check which features you need |
| Superset | Dashboards across many databases | Apache-2.0 | Self-hosted | Setup work and a learning curve |
| Metabase | Self-serve questions for non-technical teams | AGPL, enterprise directory commercial | Self-hosted open source edition | Complex queries are harder |
| Redash | SQL-first dashboards | BSD-2-Clause | Self-hosted | Every chart starts from a SQL query |
How we chose these tools
We're Snowplow, so we put Snowplow first. It solves a different part of the problem from the other 13: it collects and delivers data rather than analyzing it. We explain that difference in its section, so you can judge whether it belongs in your stack.
For every tool, we checked in November 2026:
- The license, read from the project's own LICENSE file.
- Maintenance: recent releases, and whether the repo is archived.
- A free way to use it, either self-hosted or on a free plan.
- Deployment options and how much work it takes to run.
- Fit for its category, judged from the project's documentation.
We haven't benchmarked these tools against each other, so the strengths and weak spots come from each project's documentation.
"Free and open source" covers a few different models, and this list includes all of them:
- Open source: the code is under an OSI-approved license, like Apache 2.0, MIT, GPL or BSD, and you can use it for any purpose.
- Open core: the core is open source, and some features sit in a separate directory under a paid license. PostHog, GrowthBook, Metabase and TimescaleDB work this way.
- Source-available: you can read and run the code, but the license limits how. Snowplow's pipeline and Countly Lite fall here.
- Free tiers and trials: hosted plans you don't pay for, up to a limit or for a set time. These aren't open source, but they are free.
Customer data infrastructure
1. Snowplow for owning your behavioral data
Snowplow / Snowplow GitHub / Trackers: Apache 2.0 (JavaScript tracker: BSD 3-Clause). Pipeline: source-available
Snowplow is customer data infrastructure (CDI). It collects behavioral data from your websites, apps and servers, validates and enriches every event, then loads it into your own warehouse or lake. It can also forward events to other tools in real time.
Most tools on this list analyze data: they report on events inside their own interface. Snowplow sits a step earlier. It collects, validates and delivers events, so one governed dataset can feed your warehouse and several of the tools below.
The strength of Snowplow is ownership. The data lands in your warehouse, in a structure you define, at event level. You can model it however you need and feed it to any of the analytics, testing and BI tools further down this list.
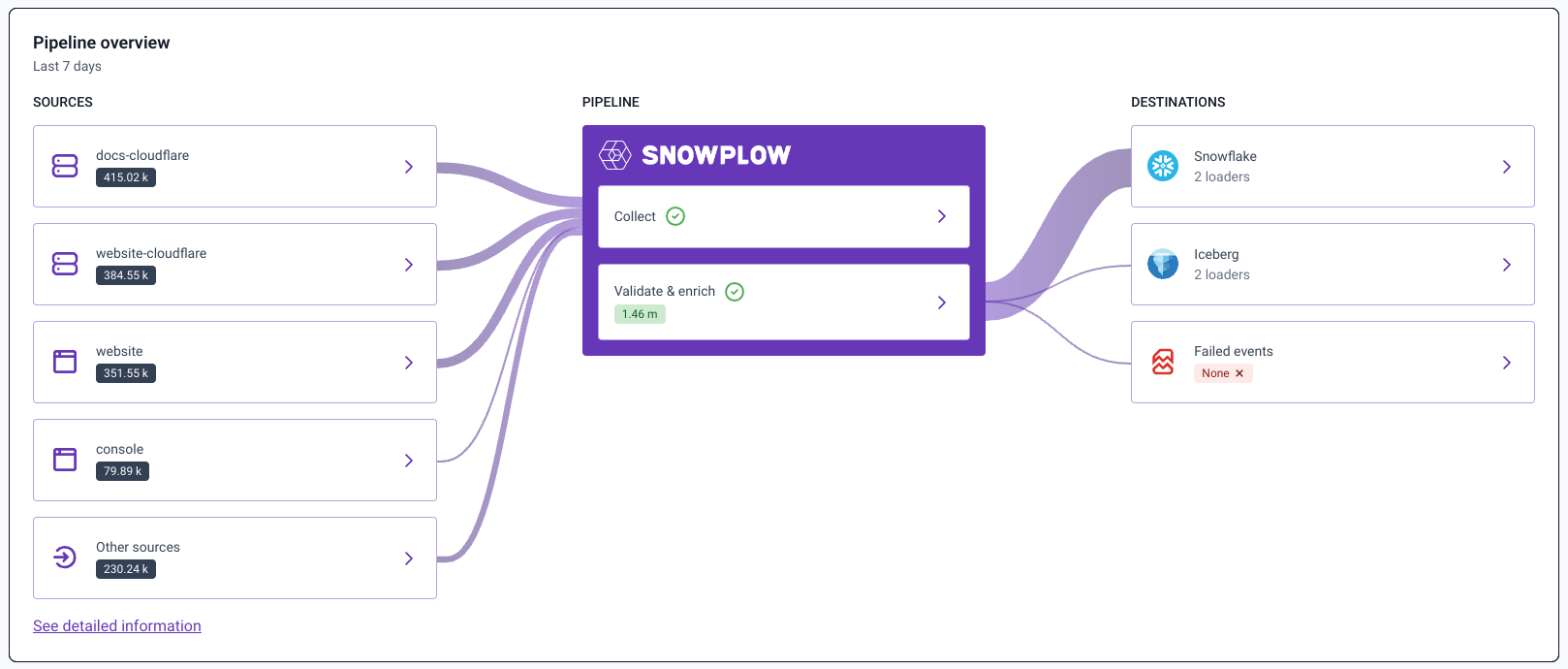
So is it open source? Partly, and it's worth being clear about which part. The tracker SDKs are open source. The pipeline apps (collector, enrichment and loaders) are source-available: you can read and run the code, but under the Snowplow Limited Use License, which covers non-production use only. Community Edition gives you a starter template for testing. For production, you run Snowplow CDI, hosted by Snowplow or in your own cloud account. We explain the reasons in our post on license changes for Snowplow open source, and compare the options in Snowplow CDI vs Snowplow open source.
The weak spot, if you're after a free production pipeline you run yourself, is exactly that: Snowplow isn't one anymore. There are two free routes. One is a 14-day trial of CDI Cloud, where Snowplow runs the pipeline for you. The other is the Signals free tier, a hosted environment with event collection included, capped at 5 million events a month.
Open source product and web analytics tools
These are entire platforms that can replace your packaged SaaS tools and give you end-to-end control over your product data. The overall pluses are control and customization. Self-hosted versions keep the data on your own servers, and you have more say over how it's analyzed. The downside is that they can take real effort to set up and run. For a wider list that includes paid tools, see our roundups of the best product analytics tools and the best web analytics tools.
2. Countly for mobile analytics
Countly / Countly GitHub / AGPL-3.0 with added terms (Countly Lite)
The strength of Countly is analytics for mobile, web and desktop apps, with read and write API access to your data. It has a plugin system to extend what you collect and report on, and you can run it yourself with Docker.
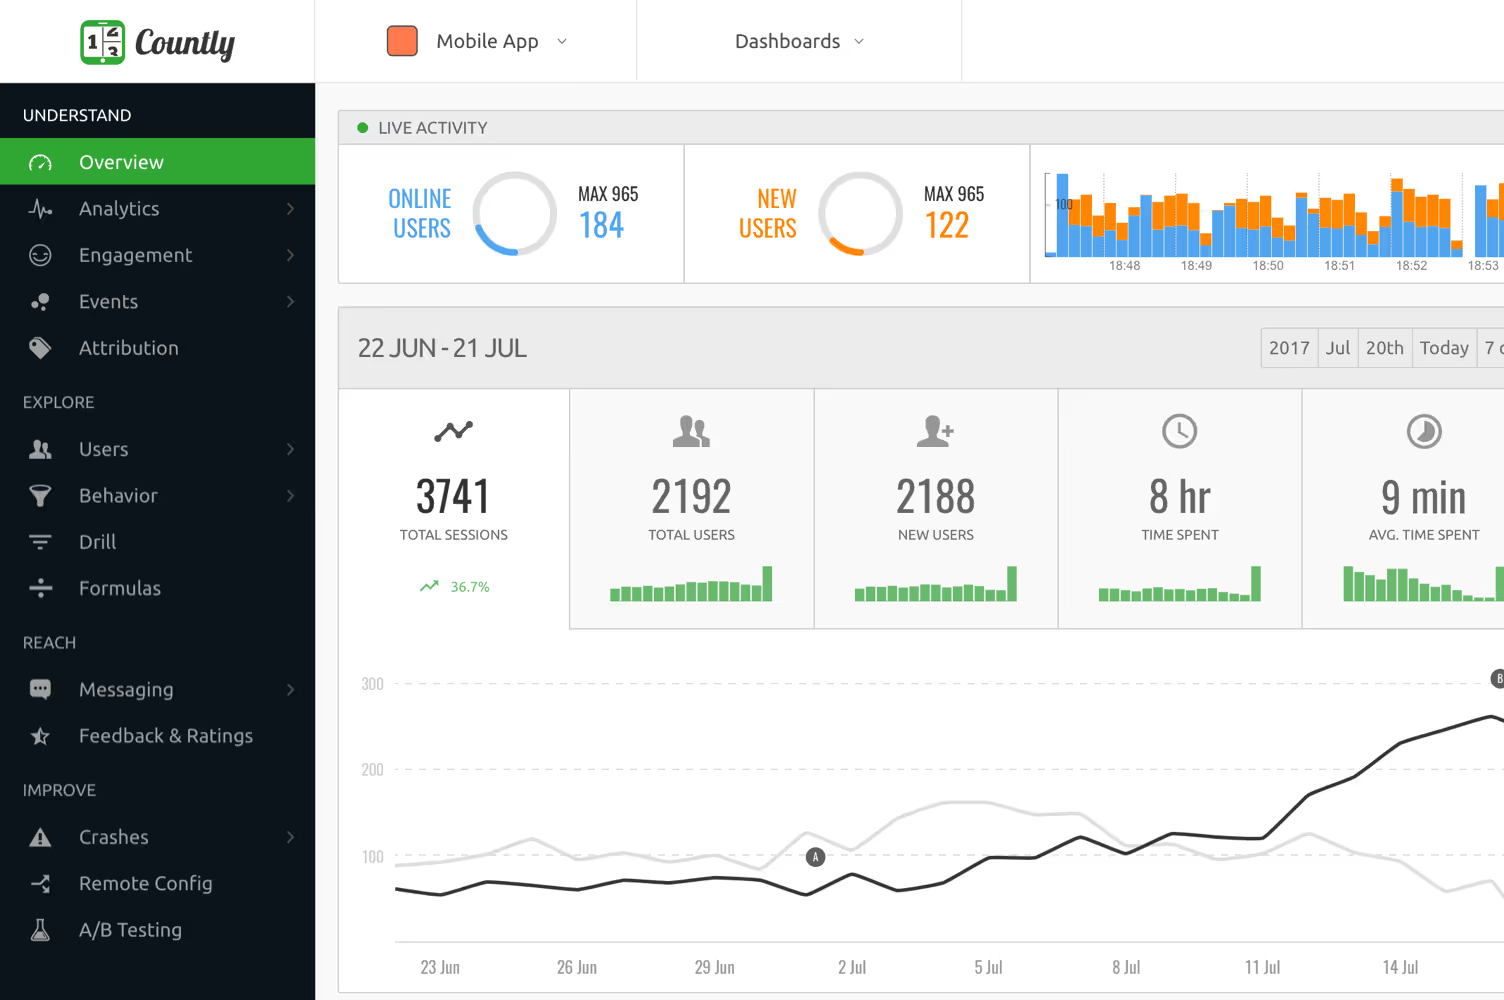
The free version is Countly Lite. Its license is AGPL-3.0 with extra terms, and Countly's own README describes it as a non-commercial license. Because of those terms, Lite isn't open source by the OSI definition, even though the code is public. Read the license before you use Lite for a commercial product. Lite also leaves out the features in the paid Enterprise edition.
3. PostHog for product analytics with a free tier
PostHog / PostHog GitHub / MIT (outside the ee/ directory)
PostHog bundles product analytics with tools like session replay and feature flags. Most teams start on PostHog Cloud, which has a monthly free tier for each product. If you want to self-host, there's a one-line "hobby" deploy for Linux with Docker. There's also a read-only PostHog FOSS repo with all proprietary code removed.
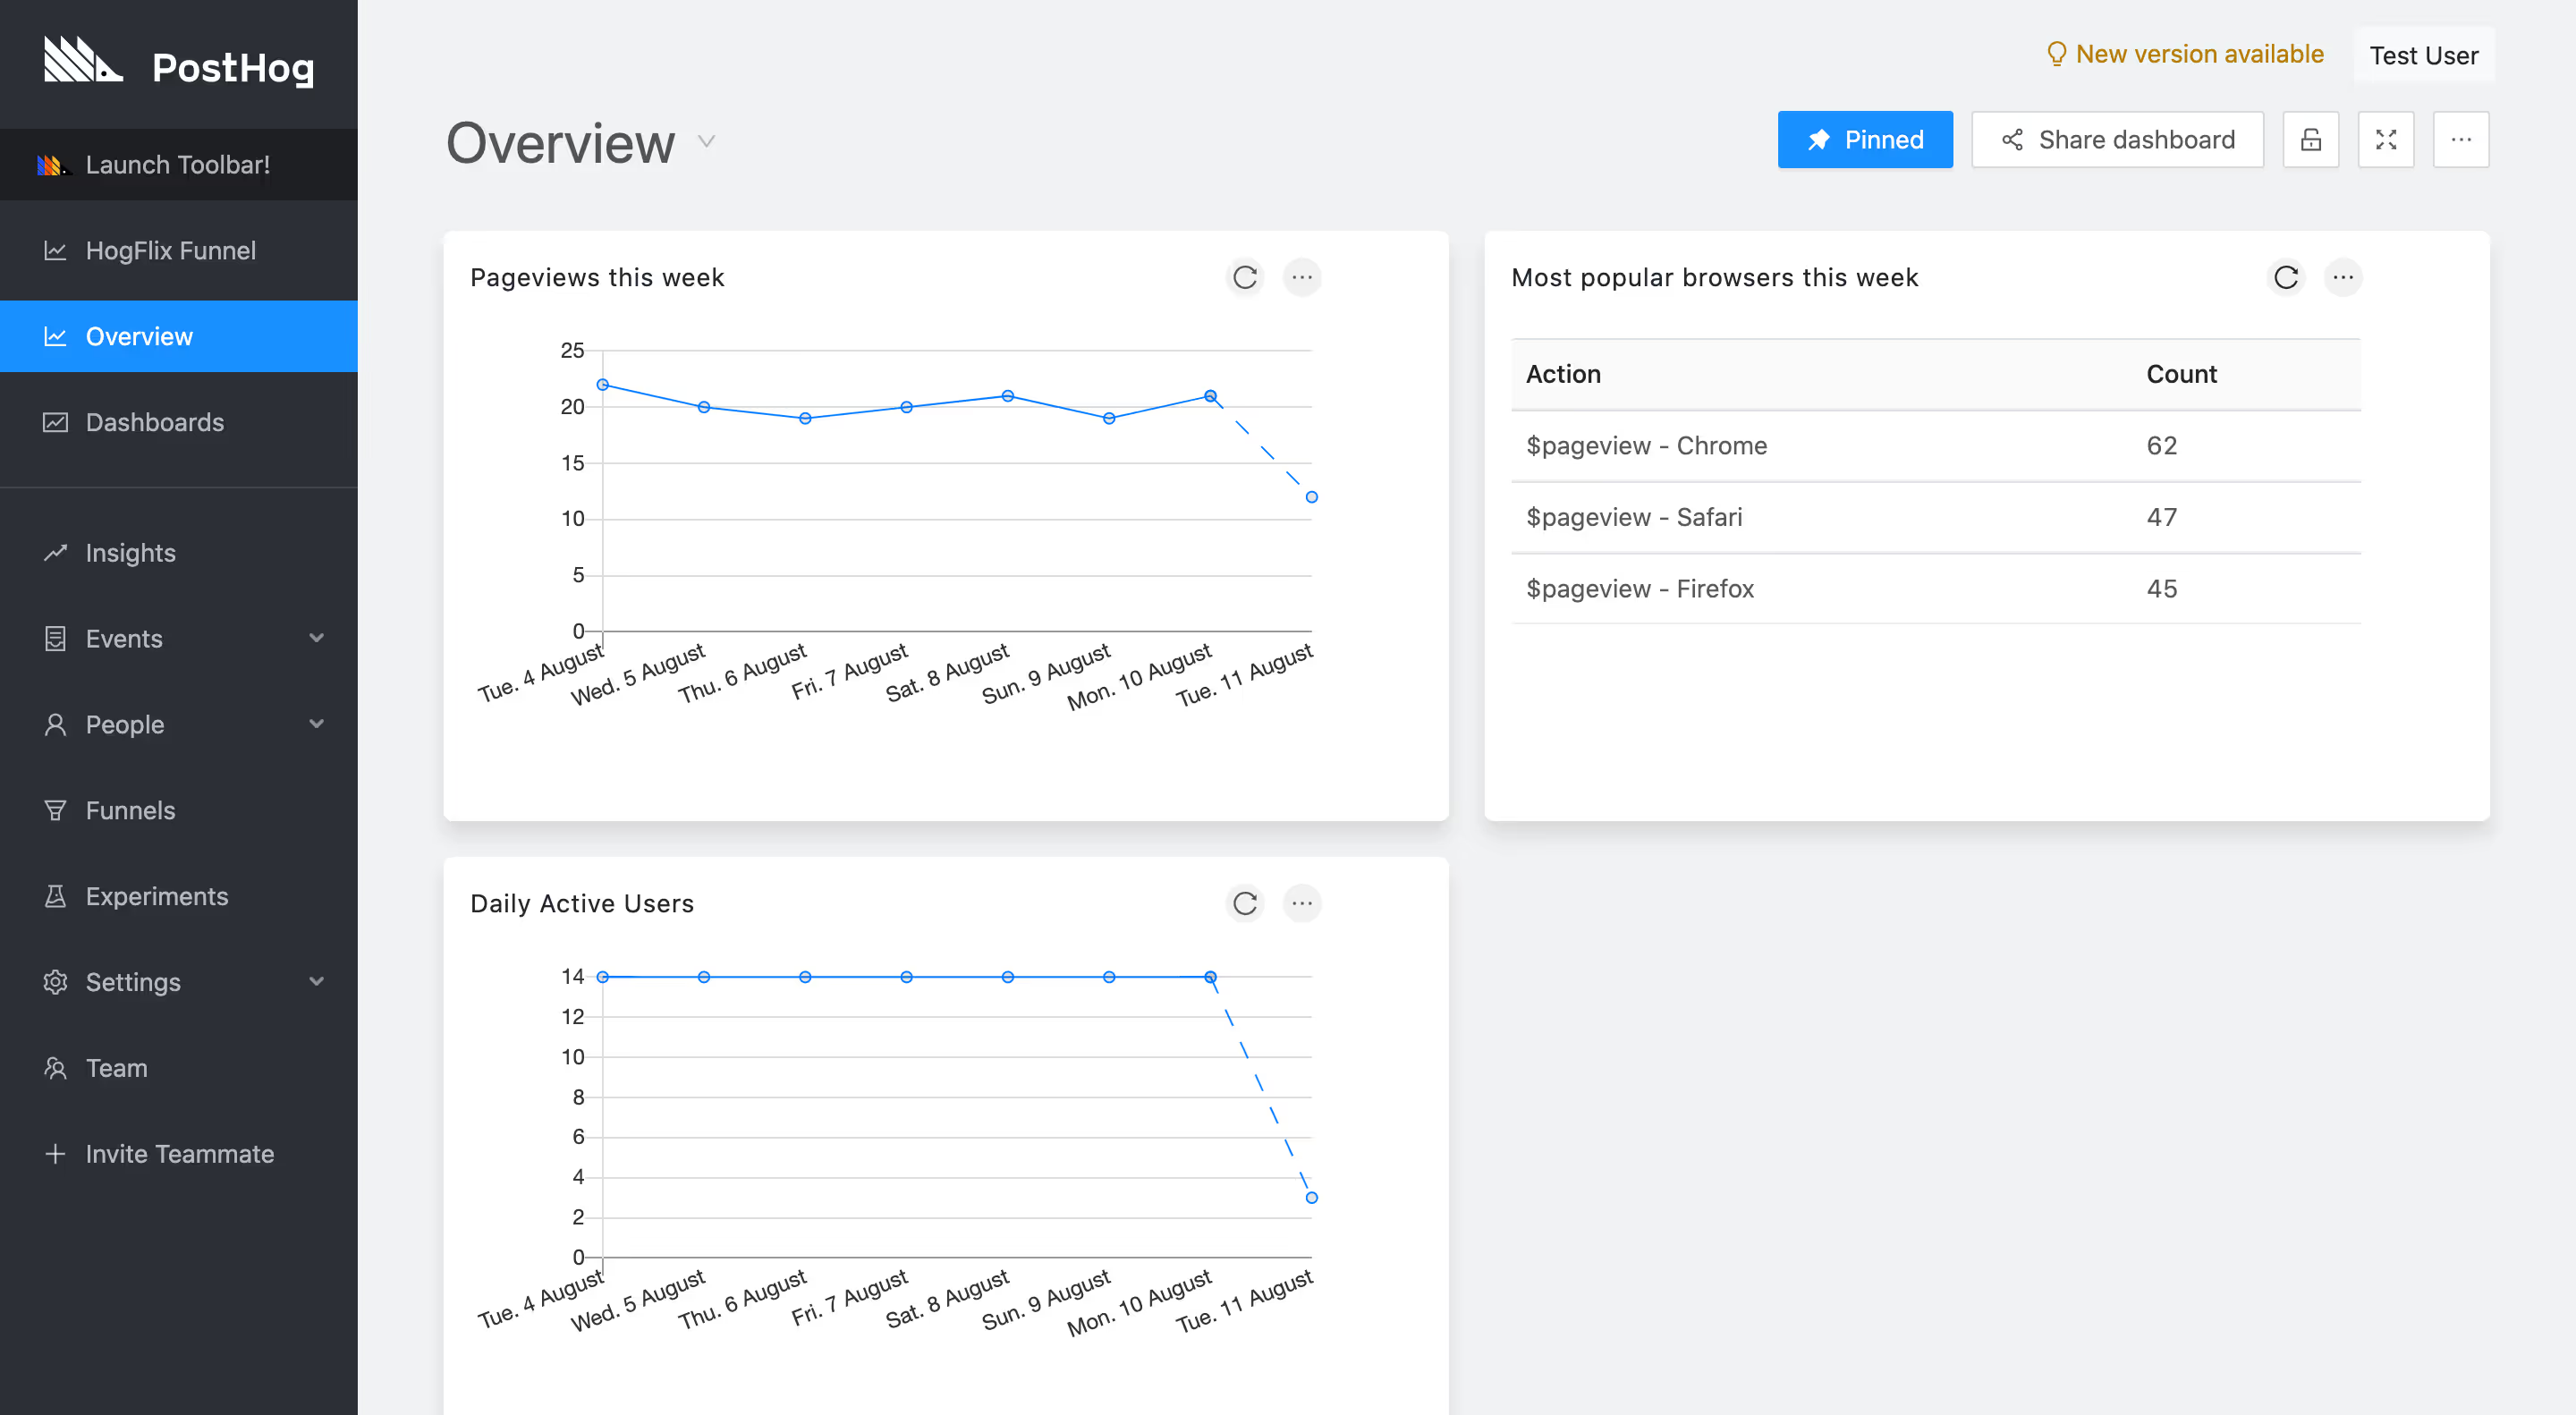
The weak spot is self-hosting. PostHog says plainly that it doesn't provide support or guarantees for open source deployments, so if your self-hosted instance breaks, it's on you.
4. Matomo for a free Google Analytics alternative
Matomo / Matomo GitHub / GPL-3.0
Matomo (formerly Piwik) is web analytics you install on your own server. It runs on PHP and MySQL, and after a short install it gives you a JavaScript tag for your site. It's one of the best known free alternatives to Google Analytics, with privacy features built in. If you'd rather not host it, Matomo Cloud is the paid hosted version.
The trade-off is the usual one for self-hosted tools. You own the PHP and MySQL stack, so upgrades, backups and scaling are your job.
If you want something lighter, two other open source web analytics tools are worth a look: Plausible (AGPL-3.0) and Umami (MIT). Both are cookie-free and privacy-first, and both can be self-hosted.
A note on "enterprise scale" analytics
If you're looking for open source analytics at enterprise scale, you might want a mesh of tools that deliver analytics data into a data warehouse, rather than a single platform. This is exactly what Snowplow was made for, and it's number 1 on this list.
That lets you build an advantage on how you collect high-quality data at scale, then use it in tools built for marketing automation, customer engagement and business intelligence. We show what this looks like for product teams in warehouse-native product analytics on Snowplow.
Open source A/B testing tools
5. GrowthBook for warehouse-native experiments
GrowthBook / GrowthBook GitHub / MIT (outside the enterprise directories)
GrowthBook combines feature flags and A/B testing. It's warehouse-native: instead of collecting its own copy of your data, it queries the warehouse you already have, including BigQuery, Snowflake and Databricks. Metrics are defined in SQL, and the stats engine supports Bayesian and sequential testing and CUPED. You can self-host it with Docker or use GrowthBook Cloud.
If you don't have a warehouse yet, GrowthBook Cloud also offers a Managed Warehouse. It collects events through GrowthBook's SDKs or an ingestion API and stores them for you. It isn't available when you self-host.
The catch with the warehouse-native route is that results are only as good as the event data in your warehouse. If that data is patchy, your experiment results will be too.
Open source reverse ETL tools
6. Multiwoven for syncing warehouse data to business tools
Multiwoven / Multiwoven GitHub / AGPL-3.0
Multiwoven is an open source reverse ETL tool, positioned as an alternative to Hightouch and Census. It reads from warehouses like Databricks, Redshift and BigQuery, lets you build models to prepare the data, and syncs it to tools like Salesforce, HubSpot and Slack. You can self-host it on AWS, Azure or GCP.
It's a younger project than the paid tools it competes with, so check the connector list covers the destinations you need before you commit.
Open source data validation tools
These tools have a specific job in your data pipeline. You add them as a step to perform a single function. The plus is that they do important work you're unlikely to get from packaged SaaS tools. The downside is that each is built for one purpose, so you need several of them to cover every use case.
7. Great Expectations for data validation
Great Expectations / Great Expectations GitHub / Apache-2.0
The strength of Great Expectations (apart from its great name) is that you can set validation rules for your data, called expectations, and get alerted when your data strays from them. The open source library is now called GX Core.
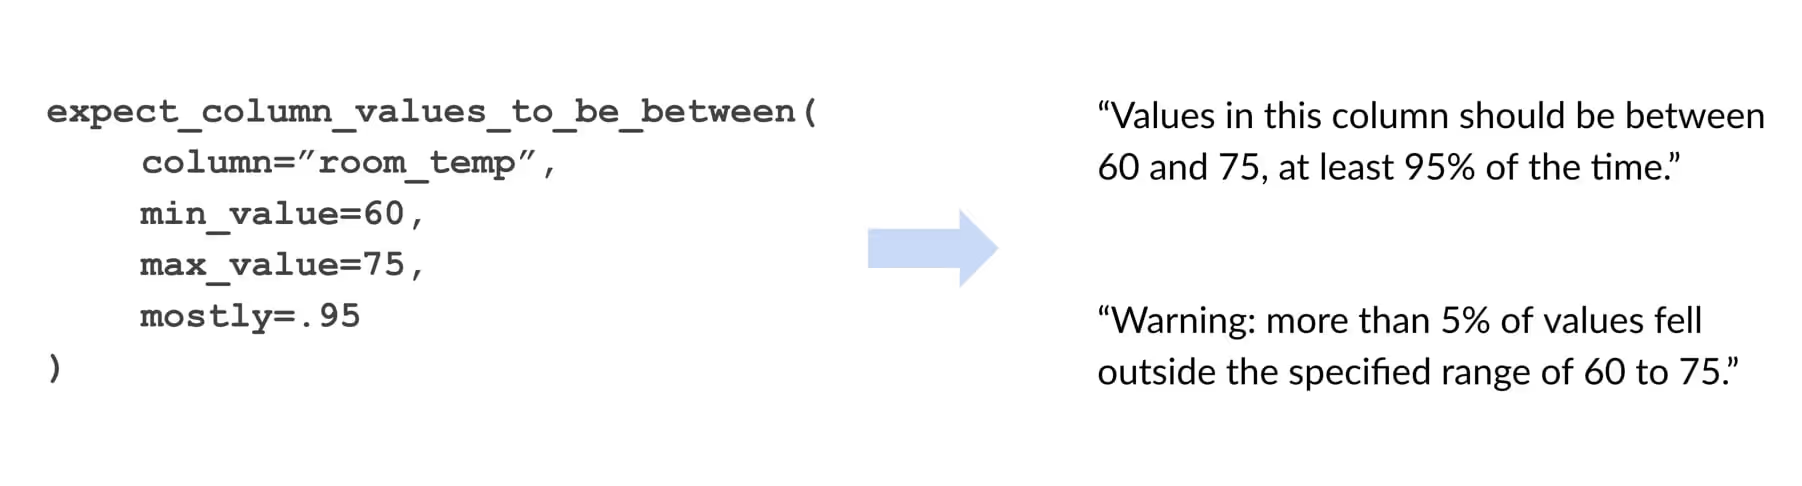
GX Core is a Python library, so whoever writes and maintains the expectations needs to be comfortable in Python.
Open source analytics engineering tools
8. dbt for analytics engineering workflows
dbt / dbt GitHub / Apache-2.0
dbt's strength is that it brings engineering practices, like version control, testing and separate development environments, into your data transformations. You write business logic in SQL and can test changes in a development environment before they reach production tables, as long as your environments are set up that way.
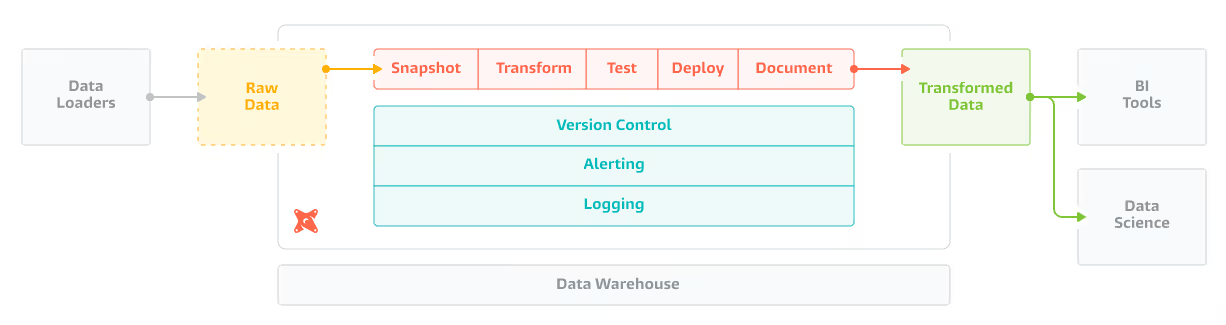
The limitation of dbt is that it only transforms data. It expects another tool to extract and load it. That's fine, as plenty of tools do those jobs, but it's one step in a larger process.
Open source anomaly detection tools
9. Elementary for data anomaly detection
Elementary / Elementary GitHub / Apache-2.0
Elementary is data observability built on dbt. Its anomaly detection runs as native dbt tests: it collects data quality metrics such as freshness and volume, flags anomalies, and sends alerts to Slack or Microsoft Teams. It also generates an observability report with your test results and lineage.
The limitation is that it's built around dbt, so it fits best if dbt already runs your transformations. Some features, such as column-level lineage and automated ML monitoring, are only in the paid Elementary Cloud.
Open source databases
Open source databases let you store your data outside the larger proprietary warehouses. Lots of databases, such as MySQL, PostgreSQL and SQLite, are open source. The two here are different because they're built for specific types of data and analysis.
10. Apache Druid for real-time querying
Druid / Druid GitHub / Apache-2.0
The strength of Druid is real-time analytics, where a user runs many queries in quick succession and needs sub-second answers. If your product needs to analyze data on the fly, Druid is worth a look.
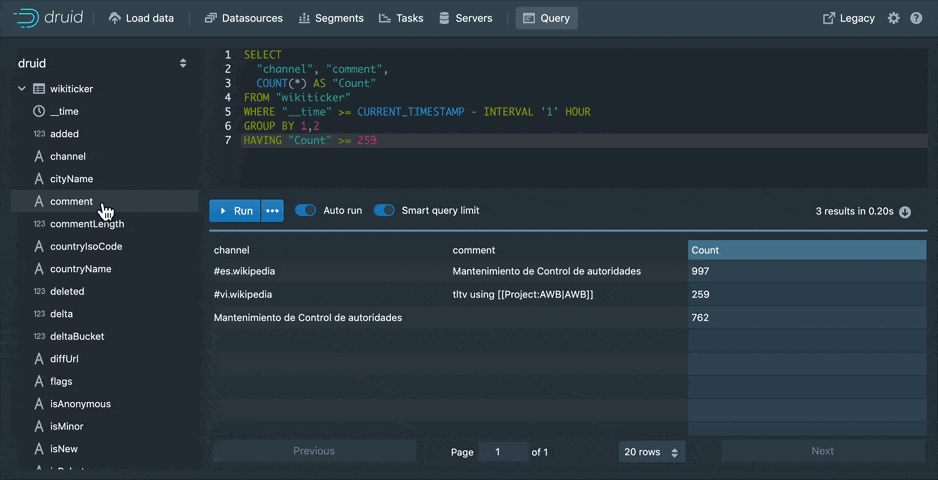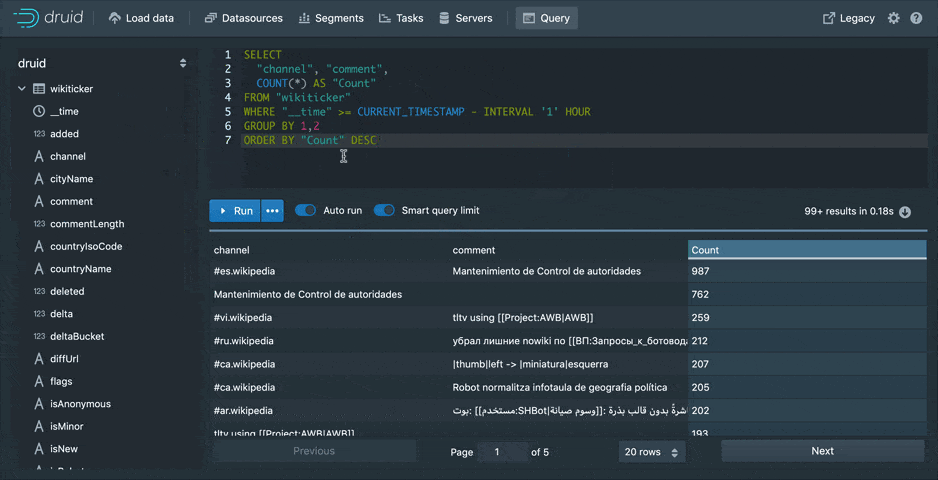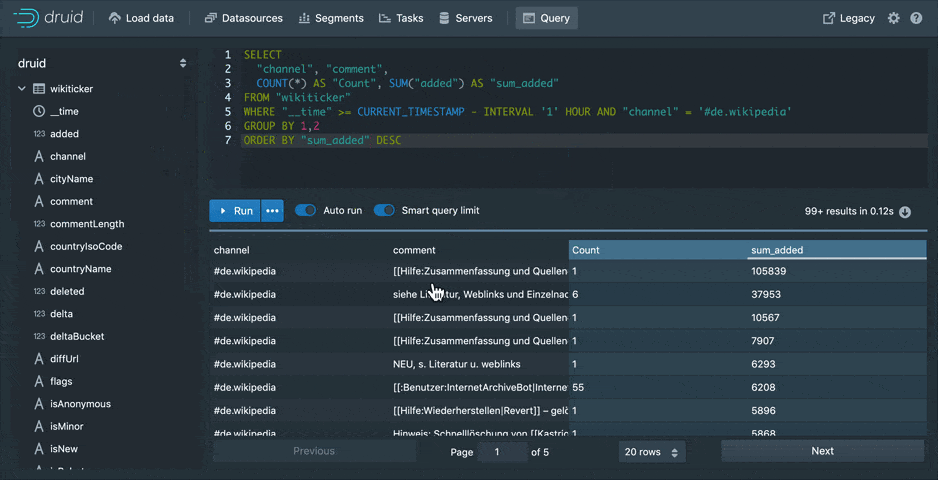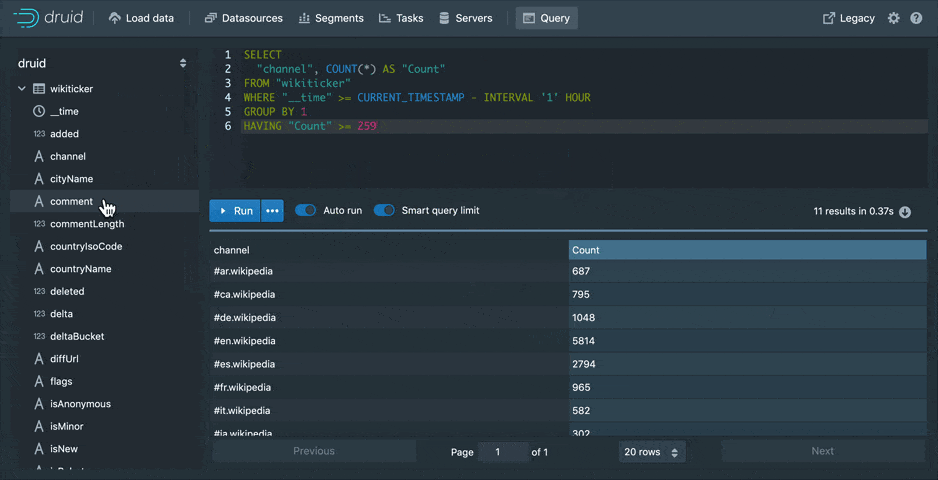
The weak spot is operational. A production Druid cluster runs several kinds of service, for queries, ingestion and storage, and depends on deep storage, a metadata database and ZooKeeper. The architecture docs show what you'd be running. That's a lot more to manage than a single-node database.
11. TimescaleDB for time-series querying
TimescaleDB / TimescaleDB GitHub / Apache-2.0 (some features under the Timescale License)
TimescaleDB's strength is that it's built for time-series data on top of PostgreSQL. If you work with time-series data, such as ongoing product usage, it lets you run complex queries with the SQL you already know. The company behind it is now called Tiger Data.
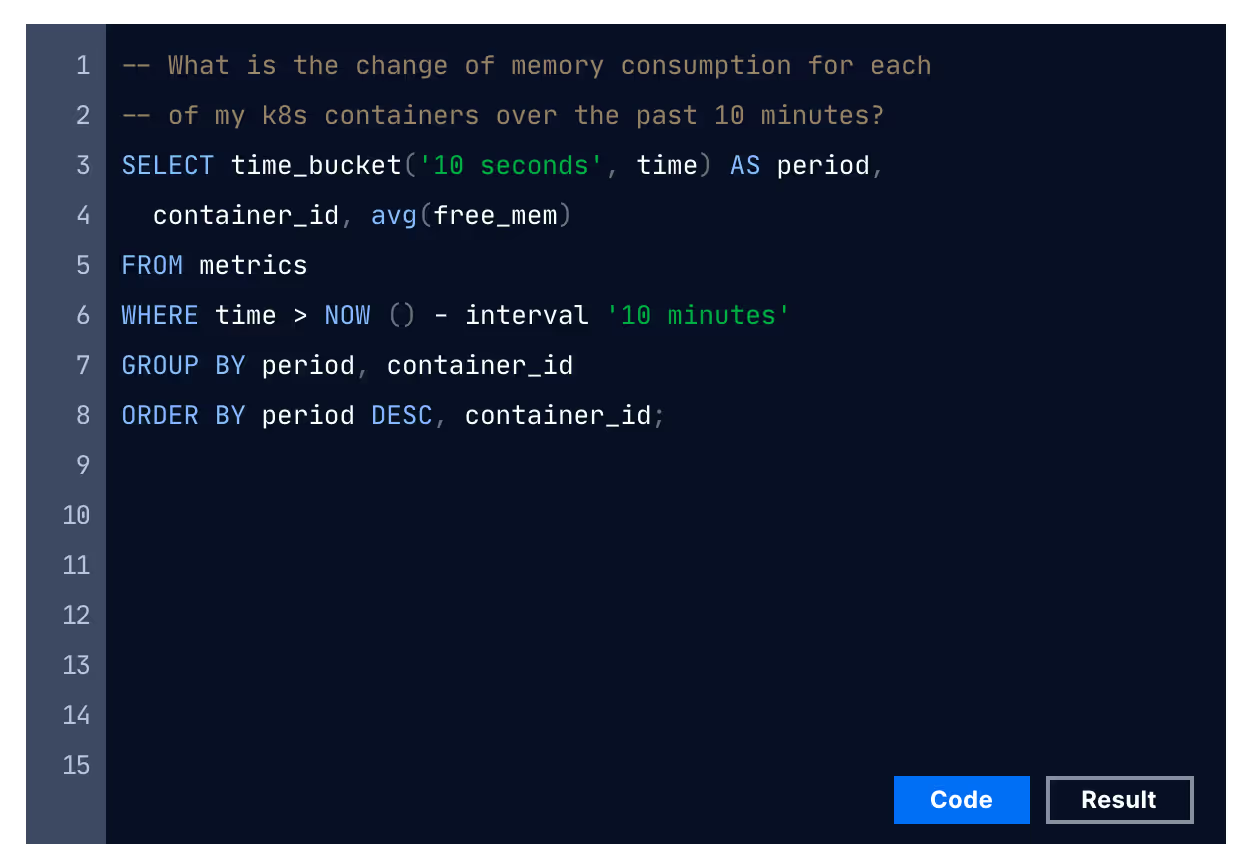
Check the license before you deploy. Code outside the repo's tsl directory is Apache 2.0, but some features sit under the Timescale License, which isn't an open source license.
Open source data visualization tools
For any analysis, you want to query and visualize the data. Proprietary BI tools such as Looker and Tableau are very popular, but so are some open source visualization tools. These three are among the most starred open source analytics projects on GitHub.
12. Superset for visualizing data in any database
Superset / Superset GitHub / Apache-2.0
The main strength of Superset is that it connects to dozens of databases, so wherever your data lives, you can visualize it. You can also put charts from different databases on the same dashboard.
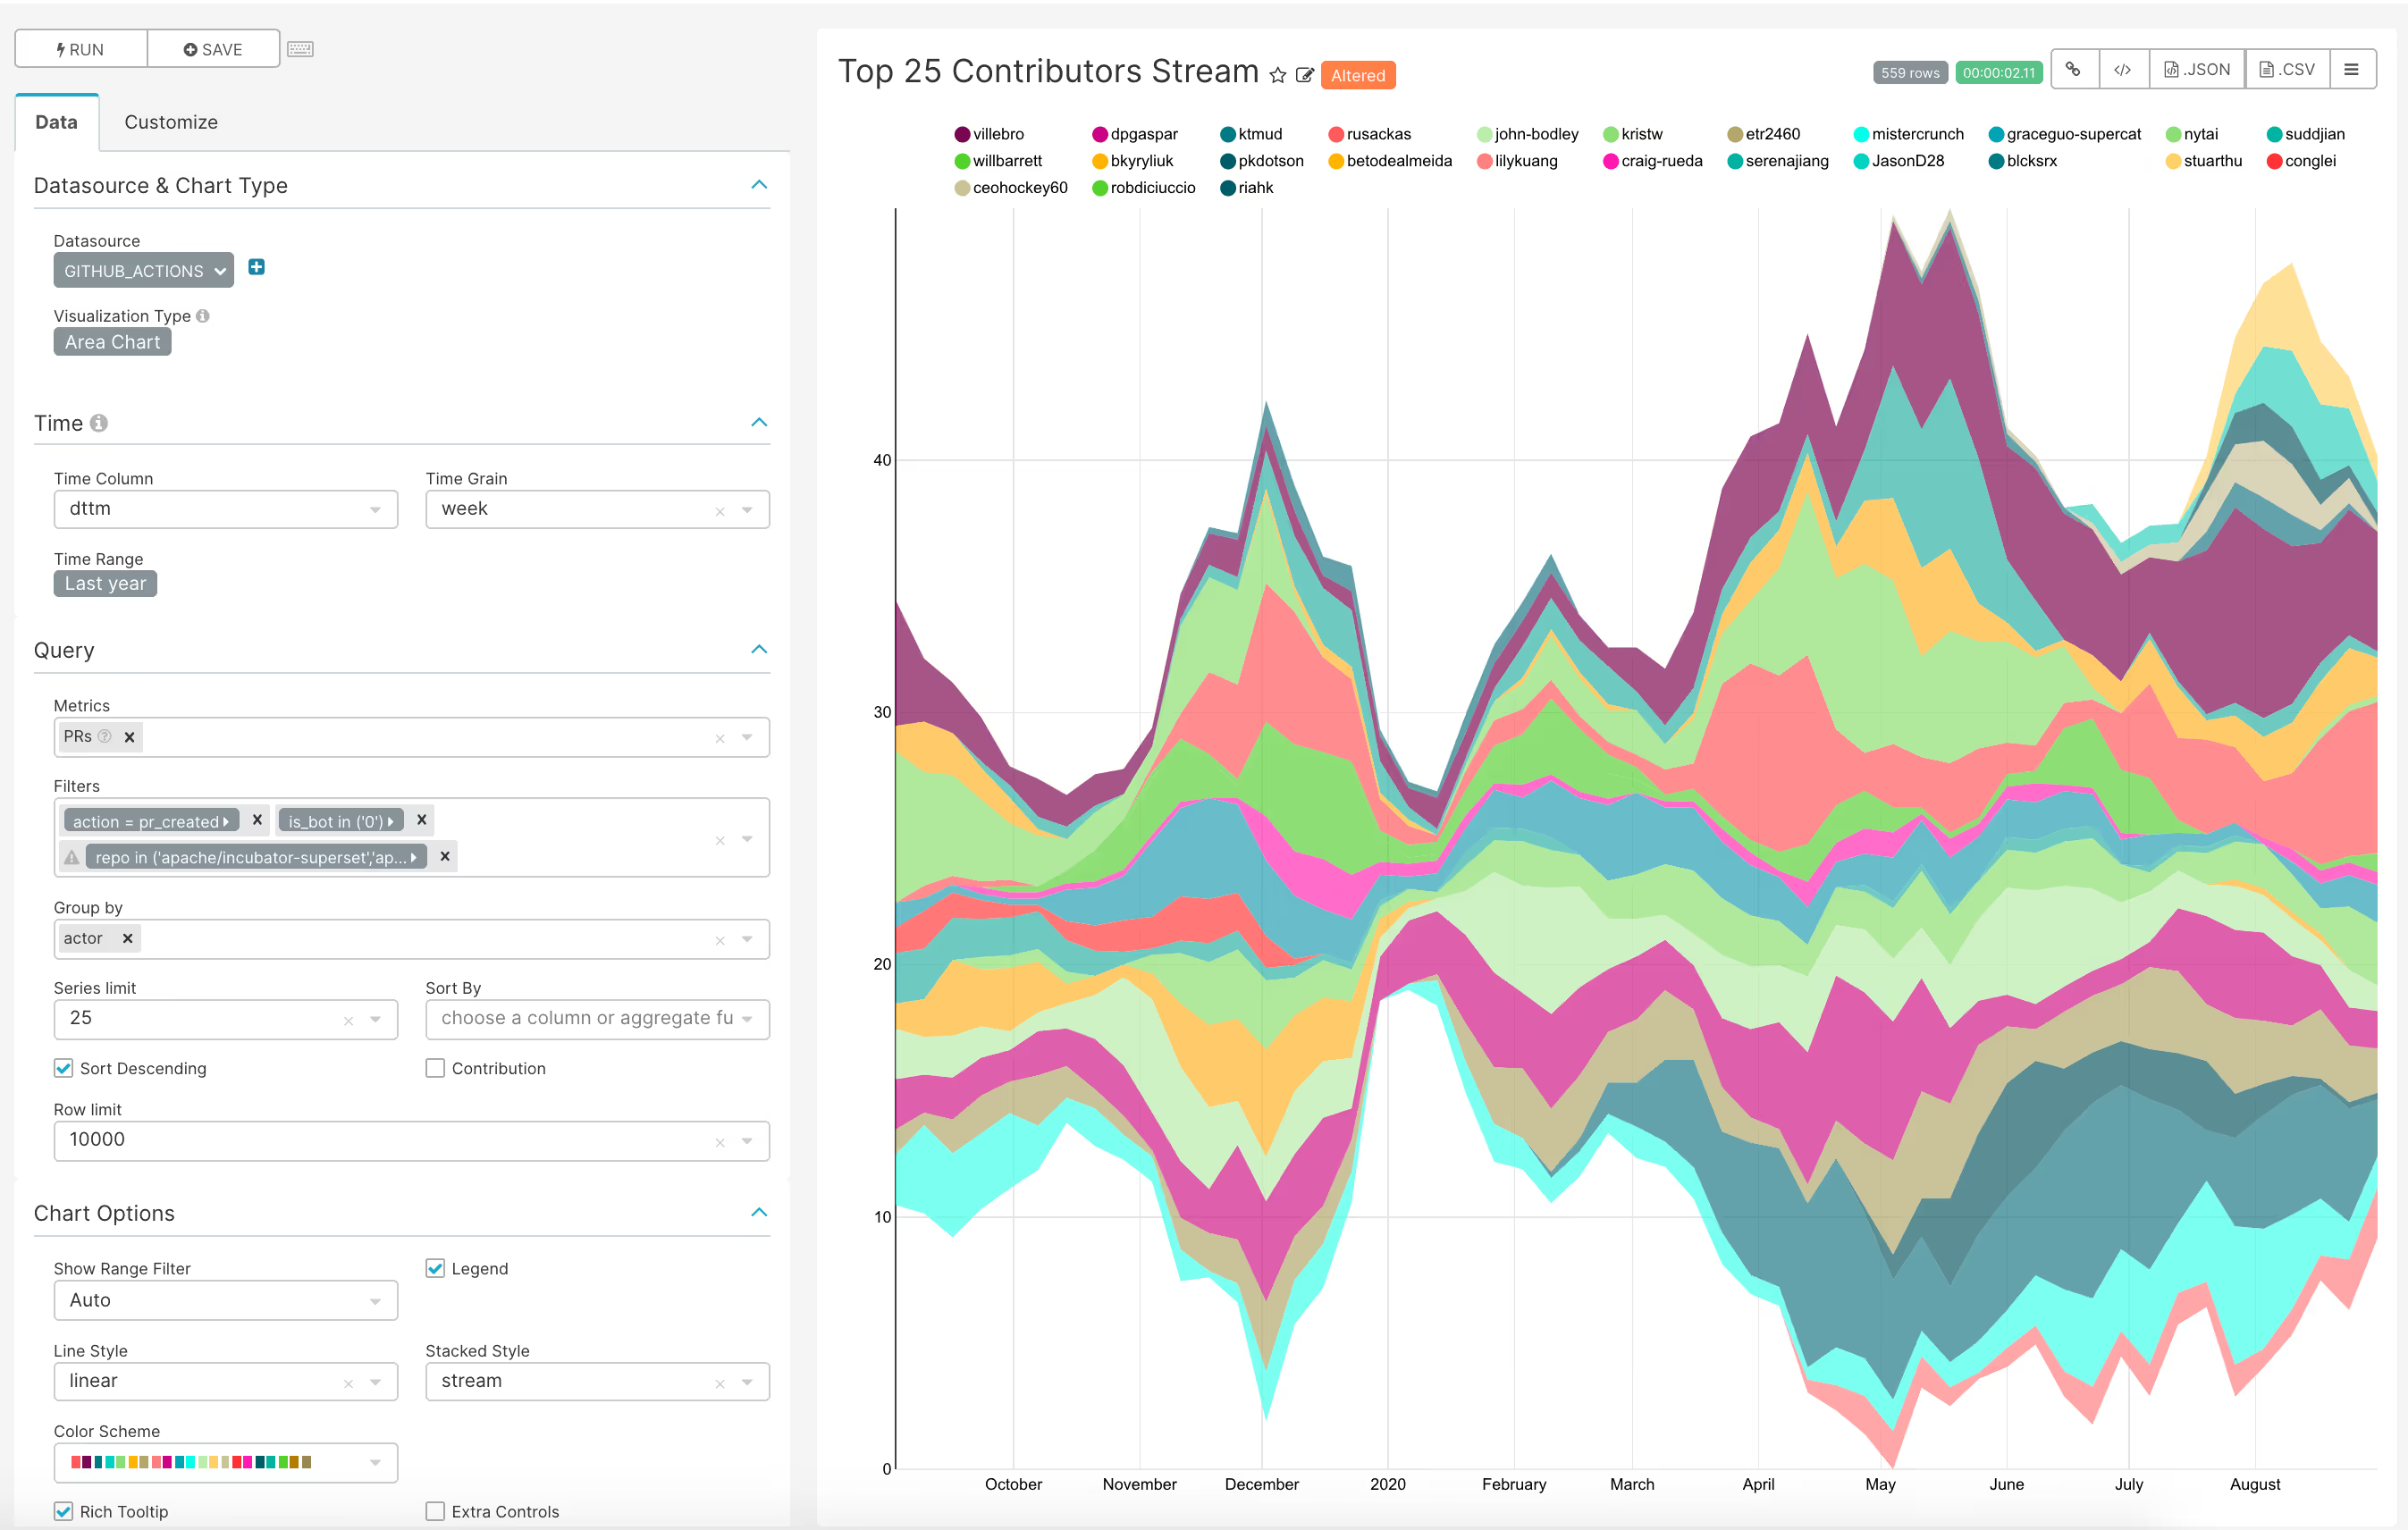
Setup takes some work, and there's a learning curve. But it's a very capable tool once you've taken the time to learn it.
13. Metabase for quick visualization
Metabase / Metabase GitHub / AGPL (enterprise directory under a commercial license)
The strength of Metabase is simplicity, both in setup and in analysis. Anyone on your team can use it to ask questions of your data and get answers.
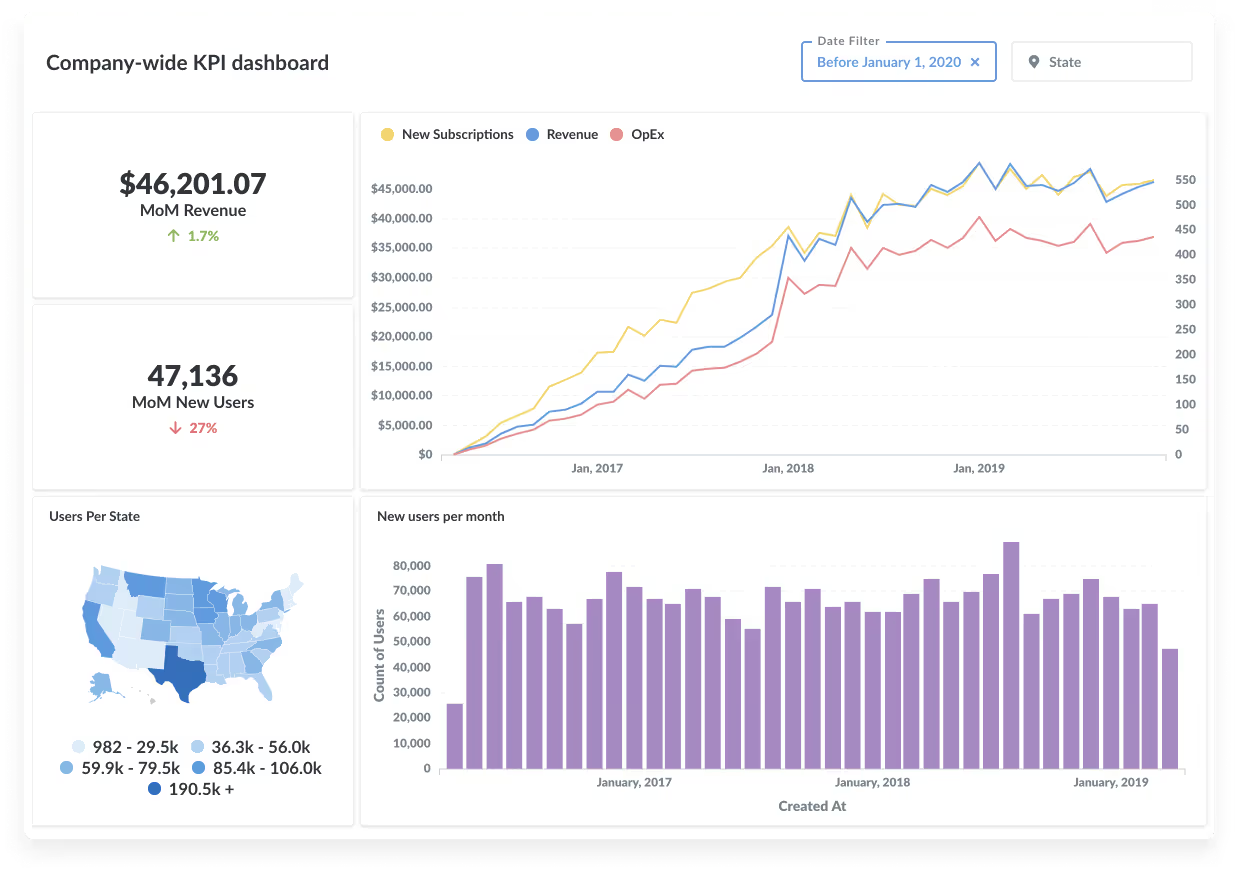
That simplicity is also its weakness: complex queries are harder. There's a SQL mode, but it isn't the center of the tool the way it is in other BI tools.
14. Redash for SQL dashboards for different teams
Redash / Redash GitHub / BSD-2-Clause
Like Metabase, the strength of Redash is ease of use. You need some SQL to get the most out of it, but you can quickly build visualizations and create separate dashboards for different teams. It's still maintained, with new releases through 2026.
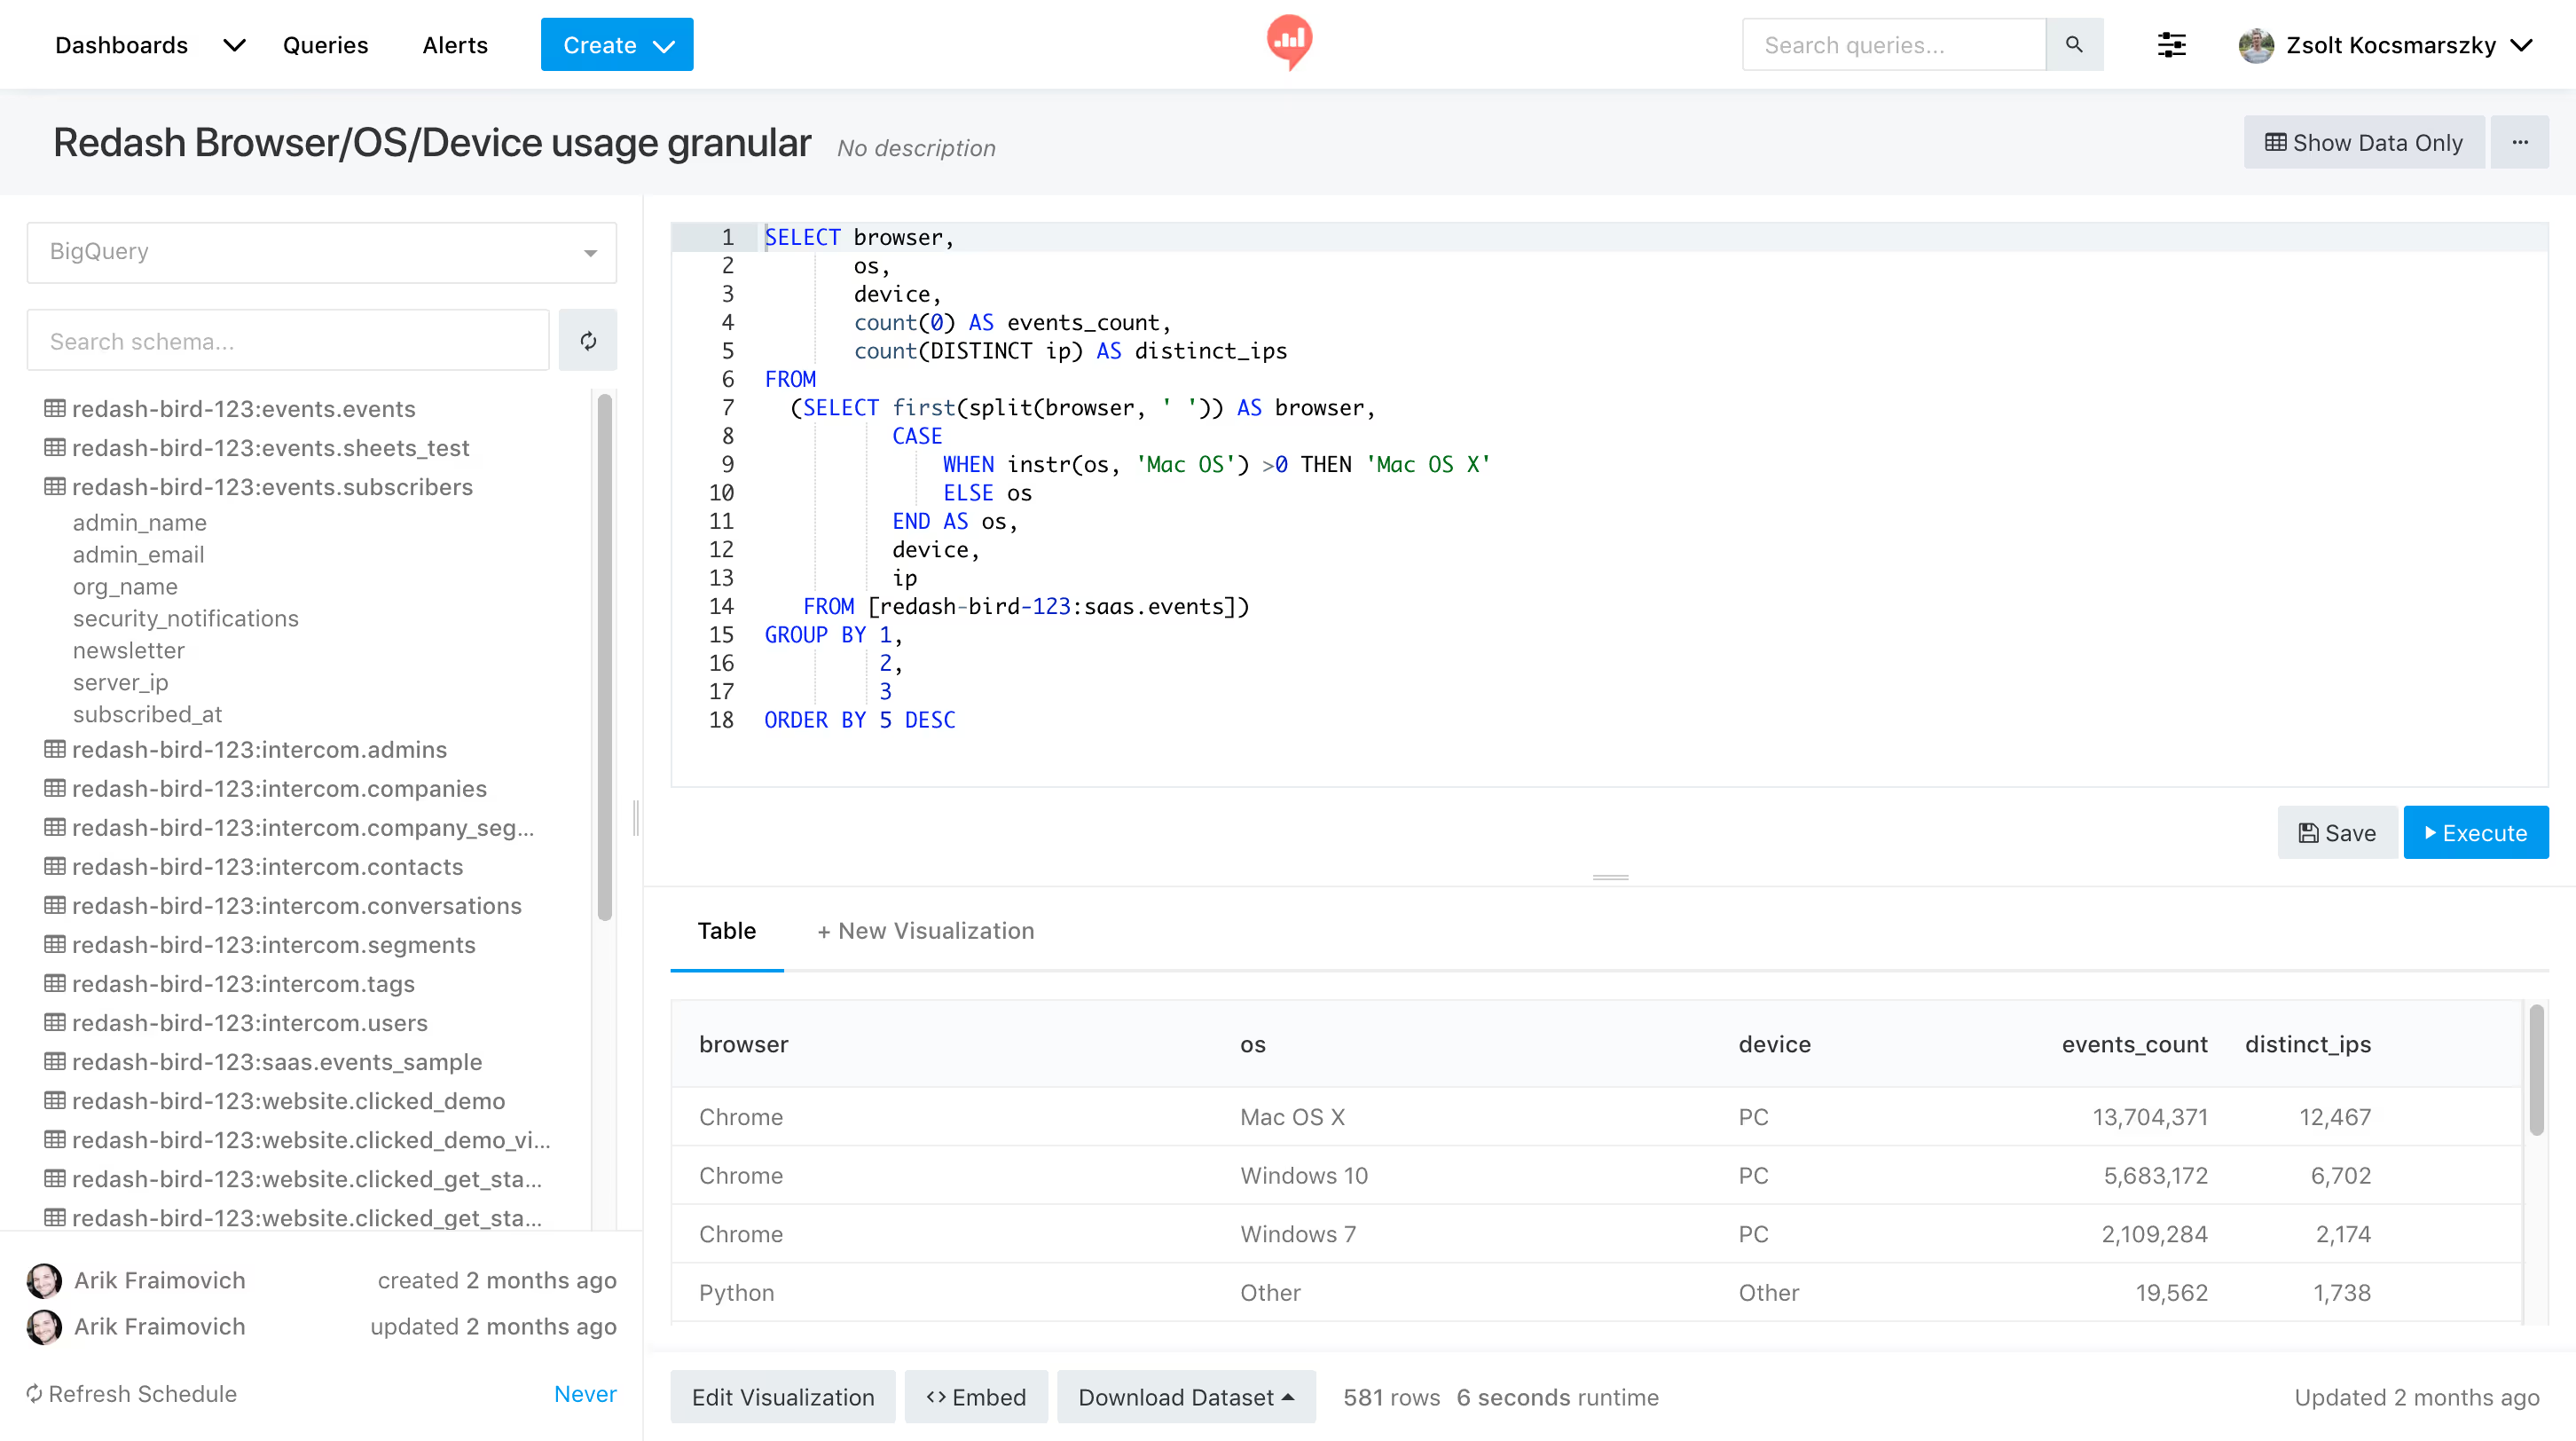
The downside is that Redash is SQL-first. Every chart starts from a query someone writes, and there's no point-and-click query builder like Metabase's, so it suits teams where people know SQL.
Open source vs hosted analytics platforms: which fits a lean team?
Open source tools cost nothing to download. The cost shows up later, in engineering time. Someone has to deploy the tool, keep it patched, scale it when traffic grows and fix it when it breaks at 2am. Some vendors, PostHog among them, say outright that they don't support self-hosted installs.
Hosted platforms flip that. You pay a subscription, and the vendor runs the infrastructure.
A rough way to decide:
- Self-host if you have engineers with spare capacity, requirements about where data is stored, or volumes that would make a hosted plan expensive. Self-hosting gives you control over where data sits, but it doesn't make you compliant on its own.
- Use a hosted plan or free tier if your team is small and nobody wants to be on call for an analytics server. Many tools here, including PostHog, Matomo and GrowthBook, offer a hosted version of the same software.
- Mix the two if you want to own the data but not the plumbing. Keep event data in your own warehouse, and pick tools that read from it.
What to look for in a free data analysis tool
- Data ownership. Can you get your raw, event-level data out, or only aggregated reports?
- The license. "Open source" gets used loosely. Check whether the license is OSI-approved (like Apache 2.0, MIT or GPL), open core with paid features in a separate directory, or source-available with limits on production or commercial use.
- Warehouse support. Does the tool read from or write to the warehouse you already use? If not, you'll end up with another copy of your data.
- Setup and running cost. Look at what it takes to run in production: servers, databases, upgrades and on-call time.
- Signs of life. Check the GitHub repo for recent releases and whether it's archived. When we refreshed this list, two of the original tools had stopped: Grouparoo's repo is archived, and Wasabi says it's no longer developed.
Take control of your data with open source tools
With some of these tools, you can get a pipeline from collection to visualization running in an hour. Others will take your data team weeks to configure.
Whatever your use case, it's worth exploring what open source can do, and the communities around these projects (forums, Slack groups, GitHub discussions) are a good place to find out what works.
Snowplow users often pair Snowplow with tools from this list. Snowplow handles the collection, validation and loading of behavioral data, and the rest of the stack works from the same governed data in your warehouse. See how it fits across use cases.
If you'd like to see what Snowplow can do for your data, try Snowplow for free or book a demo.
Frequently asked questions
What is the best free analytics tool?
It depends on the job. For website traffic, Matomo is a free, self-hosted alternative to Google Analytics. For product analytics, PostHog has a free cloud tier and an open source version. For dashboards on data you already have, Metabase and Superset are free to self-host.
Which open source analytics tools are free for commercial production use?
Tools under OSI-approved licenses, such as Matomo, Superset, Redash, Druid, dbt, GX Core and Elementary, can be run in production for free. Open core tools like PostHog, GrowthBook and Metabase are free in production too, but some features need a paid license. Countly Lite's license is non-commercial, and Snowplow's pipeline license covers non-production use only.
What's the difference between open source, open core and source-available?
Open source means the code is under an OSI-approved license and you can use it for any purpose. Open core means the core is open source but some features need a paid license. Source-available means you can read and run the code, but the license limits how, for example to non-production or non-commercial use.
What are the best analytics platforms that work with any data source?
Look at tools that read from a database or warehouse rather than collecting their own data. Superset, Metabase and Redash connect to many databases, and GrowthBook runs experiments on data in warehouses like BigQuery, Snowflake and Databricks.
Is open source analytics really free to run?
The software is free. Running it isn't. You pay for servers, storage and the engineering time to deploy, patch and scale it. Check the license too: some tools keep paid features in a separate directory, and some limit production or commercial use.